Data collection is the workload that decides which addresses you need and how they have to behave. The engineering question is narrow and answerable: what does the target treat differently, and what does that require from the estate behind the request?
This article sets out what makes a collection workload authorised, how concurrency and per-address limits interact, how session handling works for multi-step flows, and where a proxy is the wrong tool for the job.
What makes a data scraping workload authorised for a proxy gateway?
The permission you have, not the technology you use.
Authorisation comes from the terms you accepted, the data you are permitted to collect and the jurisdiction you operate in, and it exists before any request is made.
Three questions settle most cases. Is the data public, or does collecting it require an account whose terms you accepted? Are you collecting for a purpose the source permits, such as price comparison where the site allows it, or are you reproducing content that the site licenses? And does the volume you intend to collect sit inside or outside the rate the source publishes for automated access? A collection design that answers those three can proceed; one that cannot is not a technical problem with a technical solution.
The protocol layer is neutral about all of this. The proxy mechanisms used are standardised and well documented — the SOCKS5 negotiation in RFC 1928, with its authentication method in RFC 1929 — and neither specification decides whether a collection is permitted. That decision sits with the terms of the source and the law of the market, and it is worth recording rather than assuming.
| Question | What a positive answer means | Where it is recorded |
|---|---|---|
| Is the data public? | No account terms are involved | Source inventory |
| Do the terms permit the purpose? | The use is within what the source allows | Compliance review |
| Is the rate within the published limit? | Volume can be planned rather than guessed | Technical design |
| Is personal data involved? | A lawful basis is required | Privacy review |
Concurrency and per-address limits
The estate is sized by how many requests one address can make.
Concurrency is not a property of the proxy alone; it is a measure of what the target will accept from one address in a period.
That figure is the one worth measuring, because it determines the estate rather than the other way around. Where a target accepts a modest number of requests per address per minute, the estate size follows from the required rate divided by that allowance. Where the target is more permissive, fewer addresses are needed, and where it is strict, more are — and the difference is usually large enough to change the hardware decision.
Two practical consequences follow. First, the concurrency limit should be expressed per address rather than per deployment, because a global limit does not describe what any single address is doing. Second, the limit should be enforced in the scheduler rather than in the request code, because a scheduler that can hold an address out of the rotation is able to respect a limit that per-request logic cannot. The transport security that protects the management and request paths is specified in RFC 8446, with the acceptable parameters catalogued in the IANA TLS parameter registry.
Session handling for multi-step workflows
Some flows break if the address changes mid-way.
A collection that involves a session — a login, a paginated result set, a form submission — can fail if the request that follows comes from a different address.
The failure is easy to misread as a rate limit, because the symptom is a request that is rejected or a result set that appears to reset. The distinction is whether the rejection follows a change of address or a change of request rate, and the way to tell them apart is to pin one session to one address and observe. Where the flow succeeds when pinned and fails when rotated, the requirement is session affinity rather than a larger estate.
Designing for affinity has three consequences. The address has to be reserved for the duration of the session rather than allocated per request, which reduces the effective size of the estate for those flows. The reservation has to be released when the session ends, or addresses leak. And the scheduler has to be able to fall back to a new address and restart the session when an address fails, which is a retry policy rather than a rotation policy. Keeping the two separate prevents the common mistake of retrying a session on a rotating address and producing inconsistent results.
Rotation policy for this workload shape
Rotation is a policy with four parameters, as it is for any estate.
Trigger, granularity, cooldown and session awareness apply here as they do elsewhere, and for collection the last of the four is usually the deciding one.
A collection workload typically wants a rotation trigger based on request count or interval, granularity for ordinary requests and session affinity for stateful ones, and a cooldown that keeps any single address from being reused before it has rested. The combination is more nuanced than a one-size policy, and it is usually implemented as two policies: one for stateless requests and one for sessions, with the scheduler choosing based on the request type.
Where the estate is shared with other workloads, the policies should not compete. A collection job that rotates aggressively while another workload expects affinity from the same addresses produces failures that appear unrelated to either job. Separating the estates, or reserving a subset of addresses for each workload, is the practical answer, and the allocation has to be documented or it will be changed by whoever tunes the next job.
One habit keeps a collection workload defensible over time: review the target list whenever the source changes. Sites add interfaces, alter terms and introduce authentication without announcing it, and a job that was authorised when it was built may no longer be permitted a year later. Keeping the authorisation record next to the technical design means the review is a single pass rather than an archaeology exercise.
Where does a proxy fail, and what is needed instead?
When the constraint is the data rather than the address.
A proxy estate solves an addressing problem, and it does nothing for a source that requires an authenticated account, publishes an interface for the data, or blocks automated access entirely.
Three cases call for something else. Where the source offers an official interface or a data export, using it is faster, more stable and permitted, and the estate is unnecessary. Where the source requires an account and its terms restrict automated collection, no address strategy changes that; the answer is a licence or a different data source. Where the content is rendered client-side and the response contains no data, the obstacle is the rendering rather than the address, and the correct tool is a browser-based collection approach rather than a larger estate.
Recognising those three cases early avoids the most expensive mistake in this area, which is building an estate to solve a problem that addressing cannot solve. The control objectives that structure the surrounding access management, including who may run a collection job and what it may target, are organised in NIST SP 800-53 Rev. 5.
Logging that supports accountability
Which address made which request, and on whose authority.
The record that matters names the address, the target, the time and the job, so that a question about a specific request can be answered.
Two additions make the record useful rather than merely present. The first is a job identifier that ties a request to the collection task that produced it, which is what allows a question about a target to be answered without searching by address. The second is the authorisation under which the job ran, recorded once per job rather than per request, so that a review can see what the operator believed it was permitted to do.
Where personal data is involved, the record is itself personal data and its retention belongs to the same decision as the collected data. Where the processing falls within the European framework, the reference points are the regulation on EUR-Lex and the guidance collected by the European Data Protection Board. Record-keeping practice for the operational logs is covered in NIST SP 800-92.
A deployment outline
The outline follows a collection job from the authorisation to the log that shows what was retrieved. It is written around the evidence a later question about the collection would need, because the technical design follows from that rather than from the target site.
- Record the authorisation for each collection target before any request is made.
- Measure the per-address request allowance the target demonstrates.
- Derive the estate size from the required rate divided by that allowance.
- Separate stateless requests from session-bound flows, and give each its own policy.
- Reserve addresses for affinity where sessions require it, and release them when sessions end.
- Record the address, target, time and job identifier for every request.
- Decide which sources should use an official interface instead, and stop collecting from them.
The outline produces a workload design that can be operated and explained. The two items that are most often missing are the first and the last: the authorisation record and the decision not to collect from a source whose interface makes the collection unnecessary.
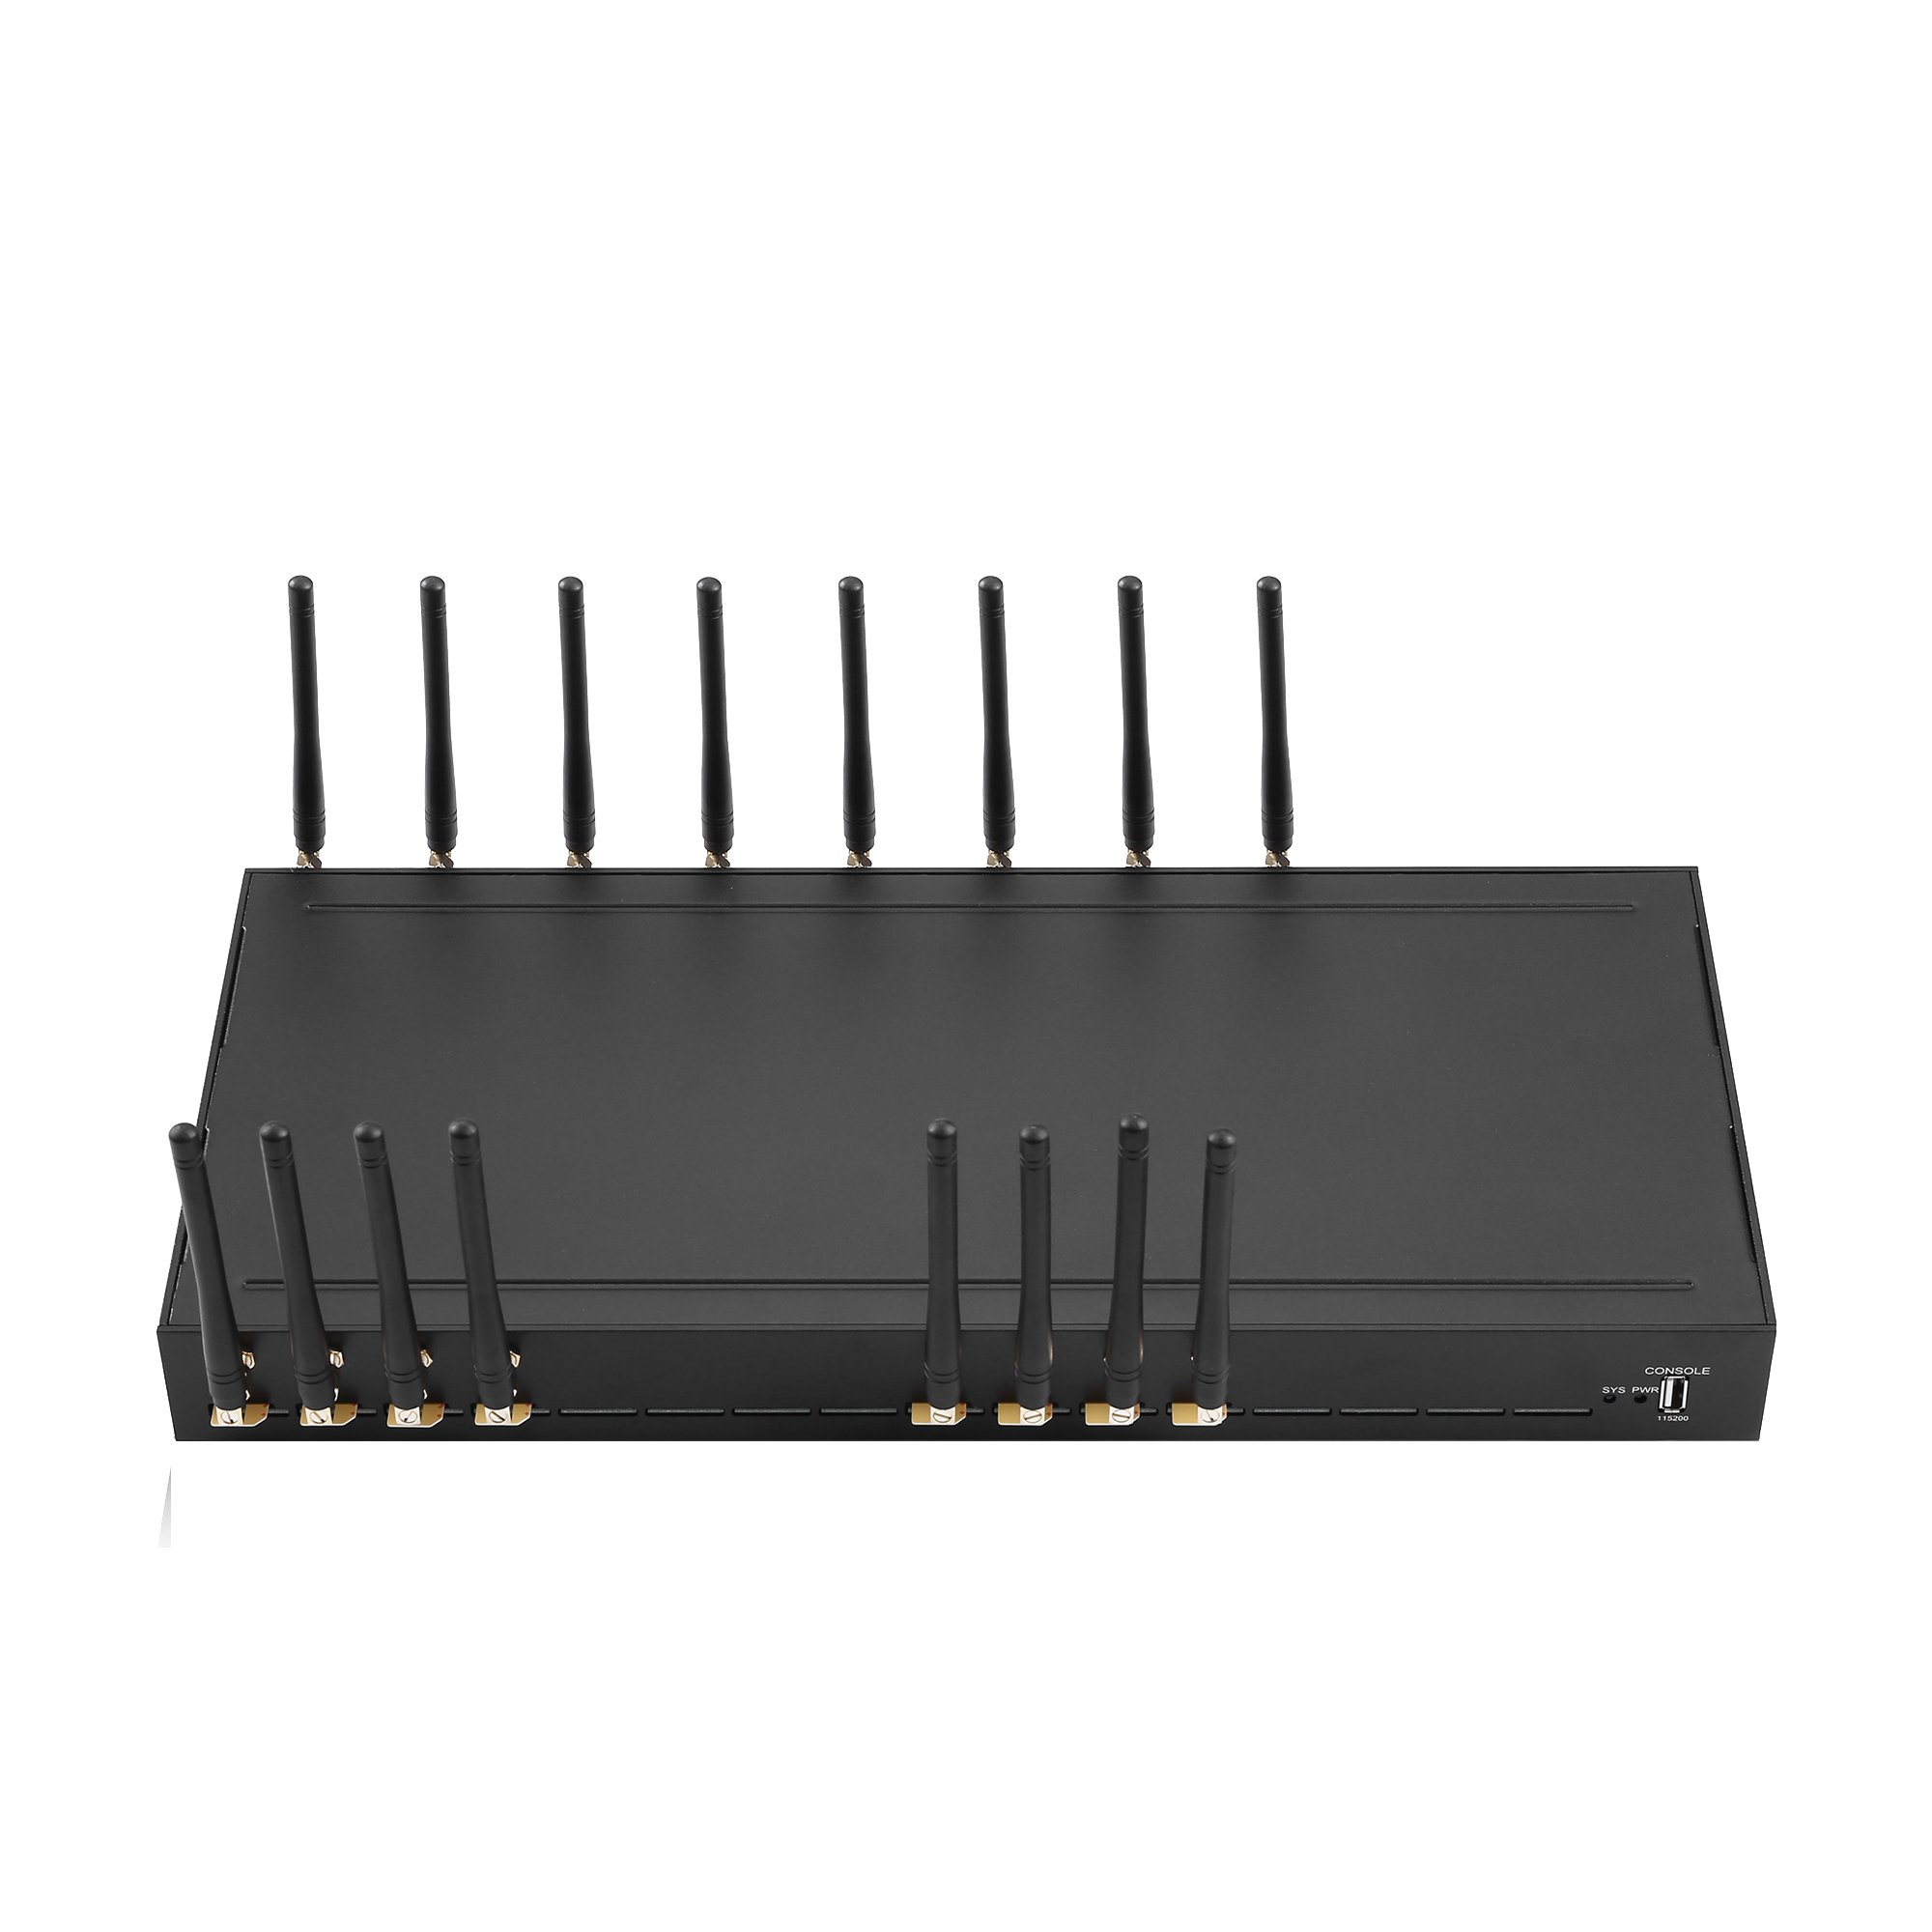
Record the authorisation before the architecture. Send your target list, required rate and session requirements to service@telarvo.com, or review the published configurations on the proxy gateway range and the proxy gateway solution page. Telarvo publishes the SK Multi WAN proxy gateway models on its product pages, and the configurations referenced above come from those listings.
FAQ
Are proxy websites illegal?
Using a proxy is not unlawful in itself. Whether a particular collection is lawful depends on what is collected, the terms the operator accepted, the jurisdiction and the lawful basis for any personal data involved. The technology is neutral, and the answer sits with the authorisation rather than with the protocol. Treat the authorisation as a document that is prepared once per job and reviewed when the target or the data changes, because the technology cannot supply it. Record who approved it and when.
Why does a collection succeed when pinned to one address and fail when rotated?
Because the flow is session-bound. Where a target ties a session to an address, a request arriving from a different address is treated as a new session or rejected. Pinning the session to one address and reserving it for the duration is the remedy, rather than adding more addresses. Record the session-to-address mapping so a later question about a specific request can be answered from the log rather than reconstructed.
Is a proxy the right tool for a site with an official API?
No. Where the source publishes an interface or an export for the data, using it is faster, more stable and permitted by the source. The estate adds cost and risk without adding capability in that case, and the honest design decision is to stop collecting from the site and use the interface. Where the interface exists, use it, and record why the collection route was chosen if the estate is retained for other work.
What should be logged for a collection workload?
The address used, the target, the time and the job identifier that produced the request, together with the authorisation recorded once per job. That set answers a question about a specific request and shows what the operator believed it was permitted to do. Keep that record for as long as a question about the collection could reasonably arise, and decide the period deliberately rather than accepting a default.